I will say here that the continuation of “this is not that hard” is still the case and if anything and as probably expected when you start looking into managed services. Don’t get me wrong I am sure if you are running multiple clusters and hundreds of nodes that might change that perception I have although the premise is still the same.
Pre-requisites
I am running everything on a Windows OS machine, as you can imagine though everything we talk about can be run on Linux, macOS and of course Windows. In some places, it can also be run in a docker container.
AWS CLI
Top of the tree is the management CLI to control all of your AWS services. Dependent on your OS you can find the instructions here.
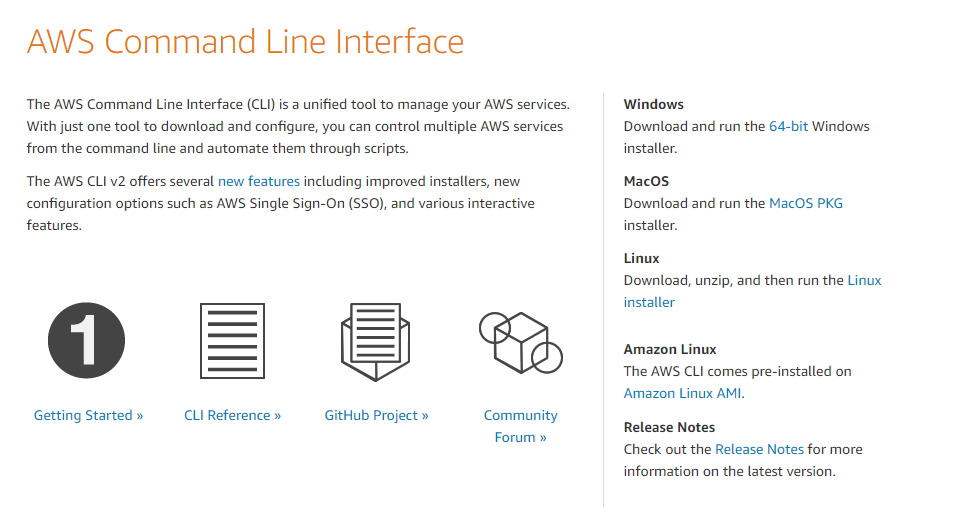
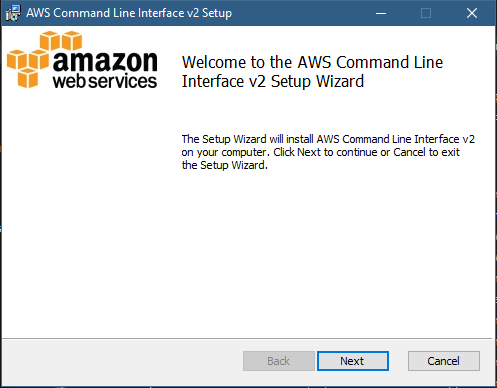
The installation is straight forward once you have the MSI downloaded. Just follow these next few steps.
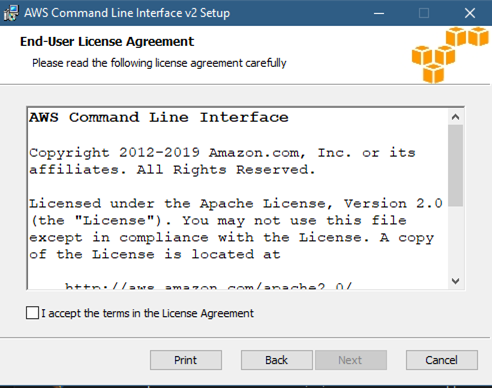
Everyone should read the license agreement. This one is a short one.
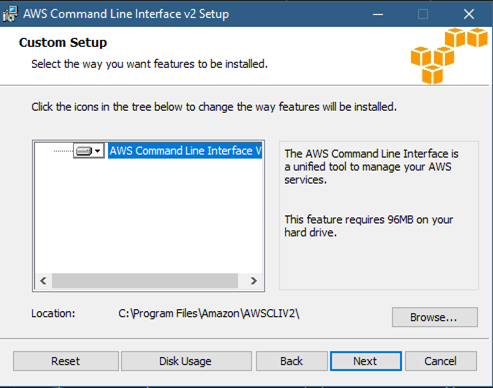
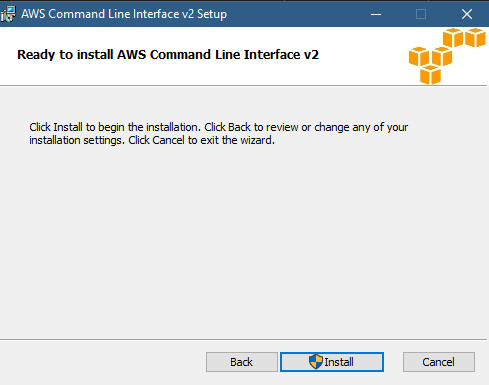
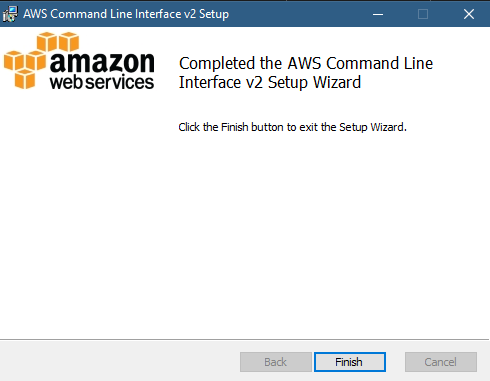
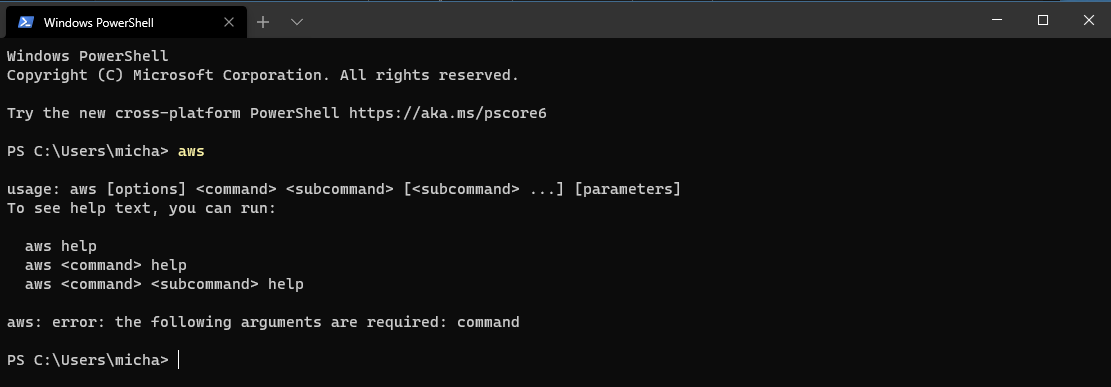
Confirm that you have installed everything successfully.
Install kubectl
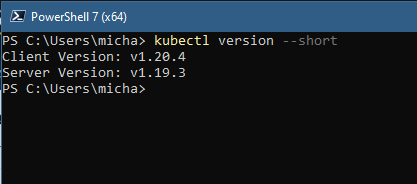
The best advice here is to check here on the version to be using within AWS EKS, you need to make sure for stable working conditions that you have the supported version of kubectl installed on your workstation. If you have been playing a lot with kubectl then you may have a newer version depending on your cluster, my workstation is using v1.20.4 as you can see below. To note it is the client version you need to focus on here. The second line (“Server Version”) contains the apiserver version.
My suggestion is to grab the latest MSI here.
Install eksctl CLI
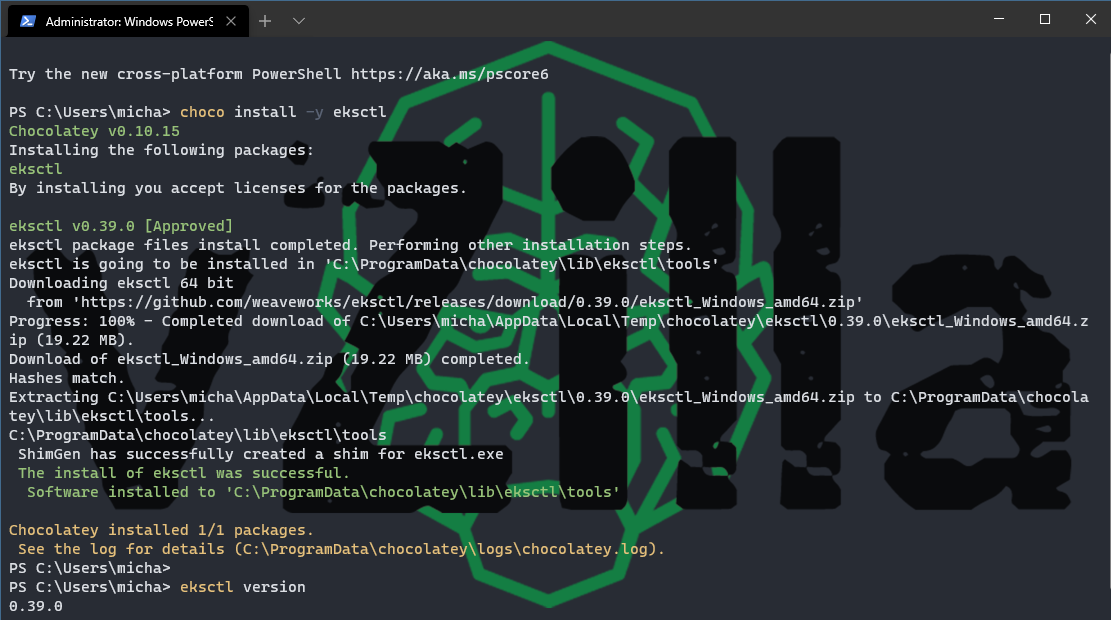
This is what we are specifically going to be using to work with our EKS cluster. Again official AWS Documentation can be found here. Again, various OS options here but we are using Windows so we will be installing eksctl using chocolatey.
IAM & VPC
Now I am not going to cover this as this would make it a monster post but you need an IAM account with specific permissions that allow you to create and manage EKS clusters in your AWS account and you need a VPC configuration. For lab and education testing, I found this walkthrough very helpful.
Let’s get to it
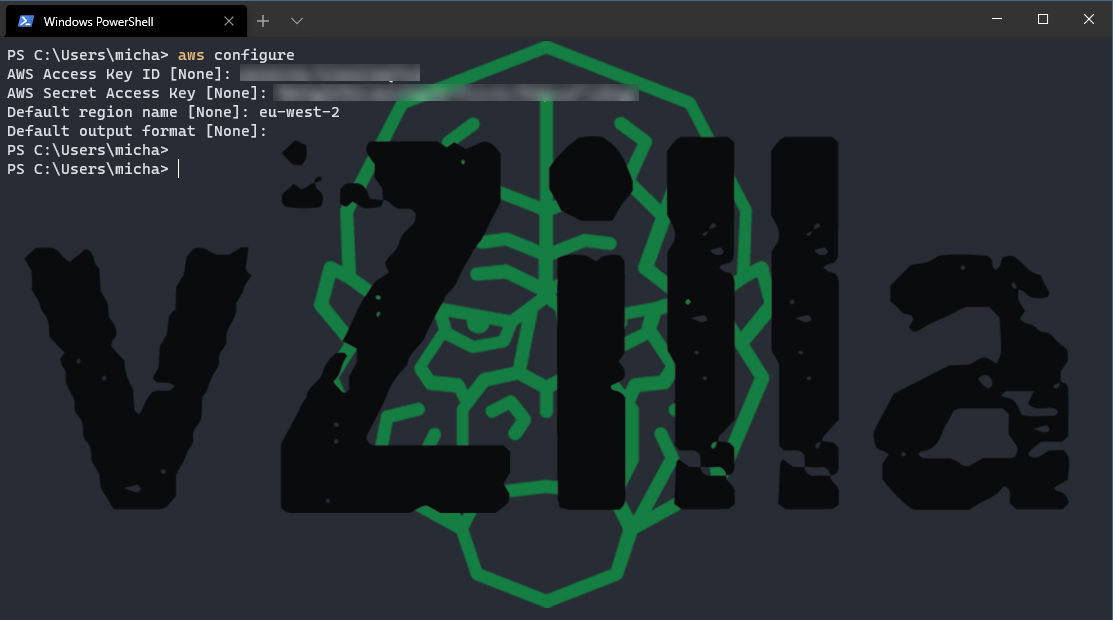
Now we have our prerequisites we can begin the next easy stages of deploying our EKS cluster. We will start by configuring our workstation AWS CLI to be able to interact with our AWS IAM along with the region we wish to use.
Next, we will use EKSCTL commands to build out our cluster, the following command is what I used for test purposes. Notice with this we will not have SSH access into our nodes as we did not specify this, but I will cover off the how on this later. This command will create a cluster called mc-eks in the eu-west-2 (London) region with a standard node group and it will use t3.small instances. This is my warning shot. If you do not specify a node type here it will use m5.large and for those using this for education then things will get costly. Another option here to really simplify things is to run eksctl create cluster and this will create an EKS cluster in your default region that we specified above with AWS CLI with one nodegroup with 2 of those monster nodes.
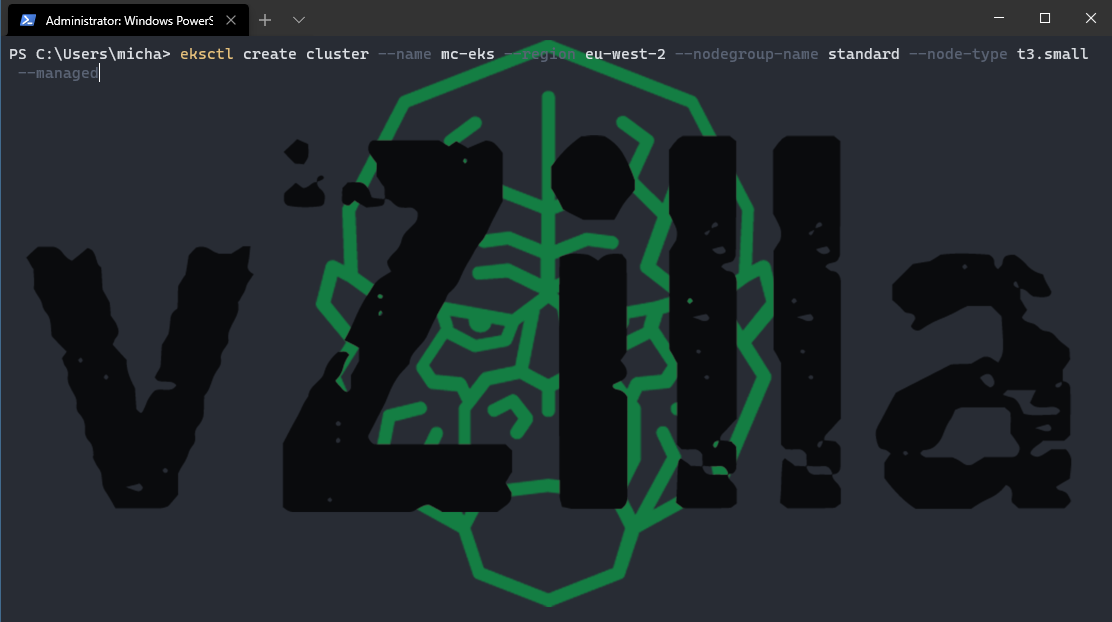
Once you are happy you have the correct command then hit enter and watch the cluster build start to commence.
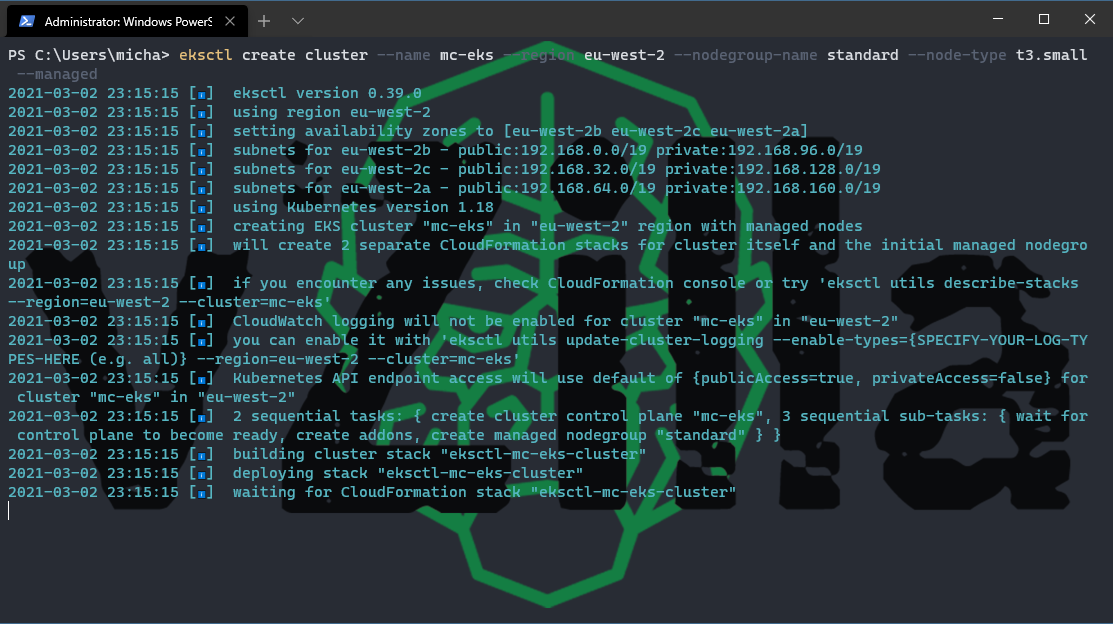
If you would like to understand what the above is then you can head into your AWS management console and location CloudFormation and here you will see the progress of your new EKS stack being created.
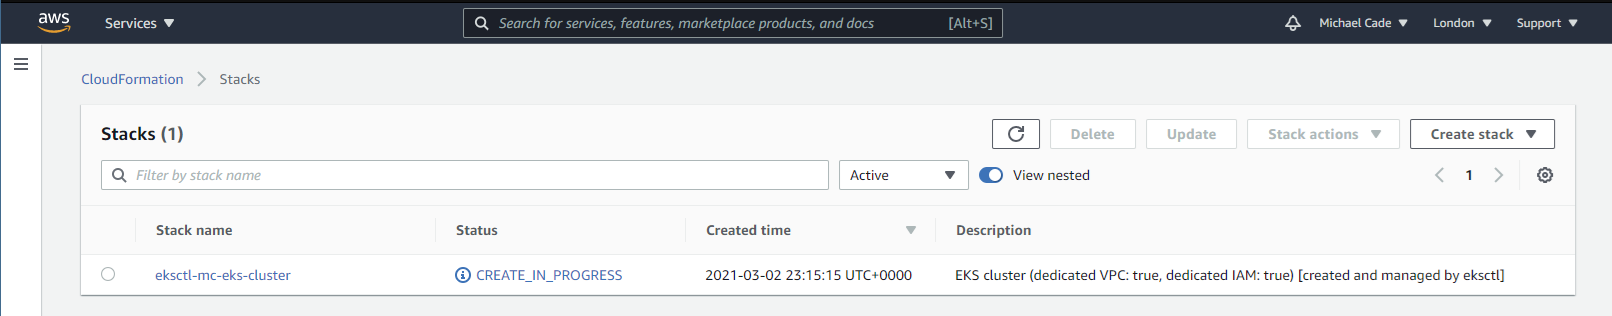
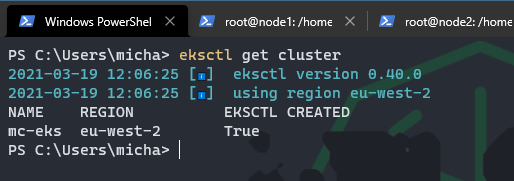
Then when this completes you will have your managed Kubernetes cluster running in AWS and accessible via your local kubectl. Because I also wanted to connect via SSH to my nodes I went with a different EKS build-out for longer-term education and plans. Here is the command that I run when I require a new EKS Cluster. To what we had above it looks similar but when I also created the IAM role I wanted the SSH key so I could connect to my nodes this is reflected in the –ssh-access being enabled and then ssh-public-key that is being used to connect. You will also notice that I am creating my cluster with 3 nodes with 1 minimum and 3 maximum. There are lots of options you can put into creating the cluster including versions
eksctl create cluster –name mc-eks –region eu-west-2 –nodegroup-name standard –managed –ssh-access –ssh-public-key=MCEKS1 –nodes 3 –nodes-min 1 –nodes-max 4
Accessing the nodes
If you did follow the above and you did get the PEM file when you created the IAM role then you can now SSH into your nodes by using a similar command to below: obviously making sure you had the correct ec2 instance and the location of your pem file.
ssh [email protected] -i C:\Users\micha\.kube\MCEKS1.pem
in order to get the public DNS name or public IP then you can run the following command, again for the note I am filtering to only show m5.large because I know this is the only instances I have running with that size ec2 instance type.
aws ec2 describe-instances –filters Name=instance-type,Values=m5.large
if these are the only machines you have running in your default region, we provided then you can just run the following command.
aws ec2 describe-instances
Accessing the Kubernetes Cluster
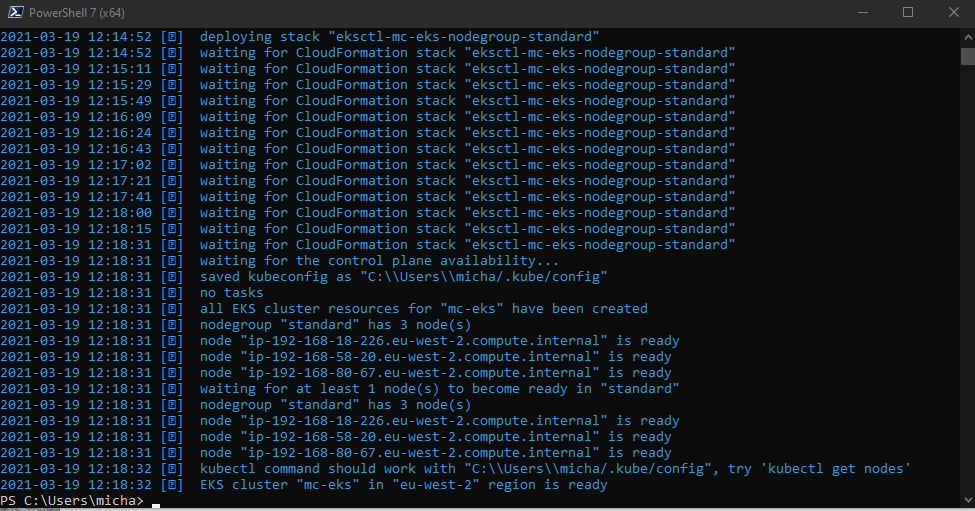
Finally we now just need to connect to our Kubernetes cluster, when you receive the end of the command we ran to create the cluster as per below
We can then check access,
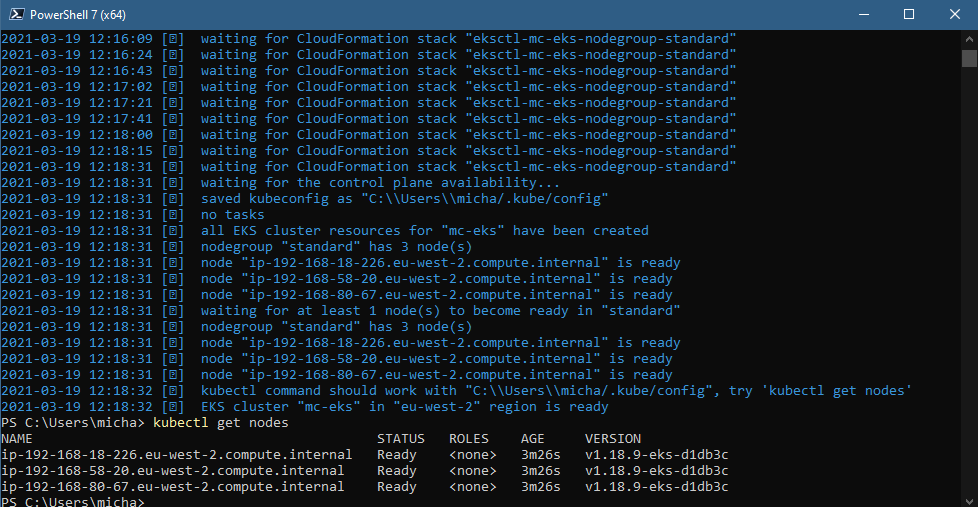
eksctl created a kubectl config file in ~/.kube or added the new cluster’s configuration within an existing config file in ~/.kube. if you already had say a home lab in your kubectl config then you can see this or switch to this using the following commands. Also covered in a previous post about contexts.
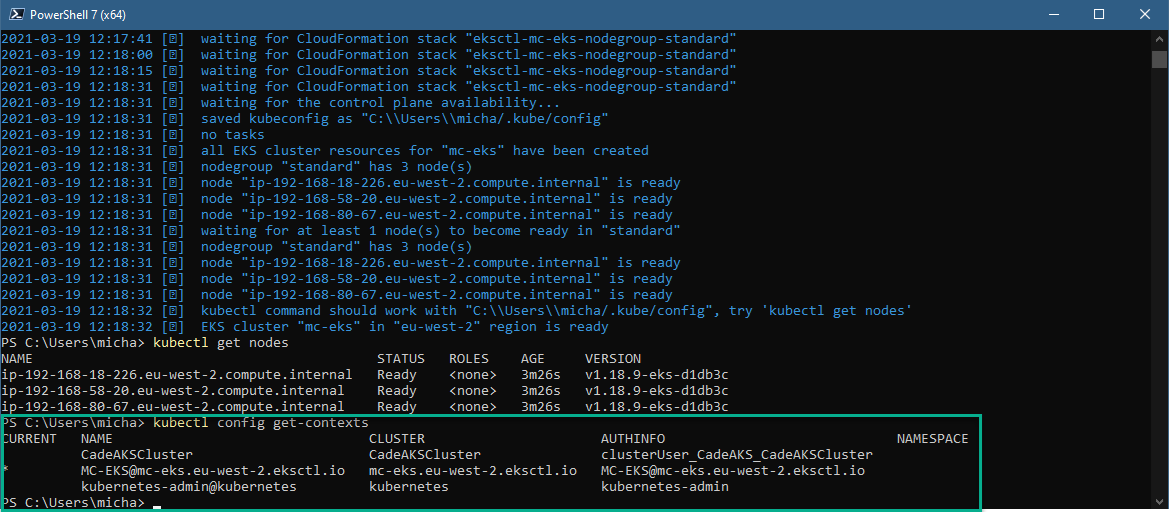
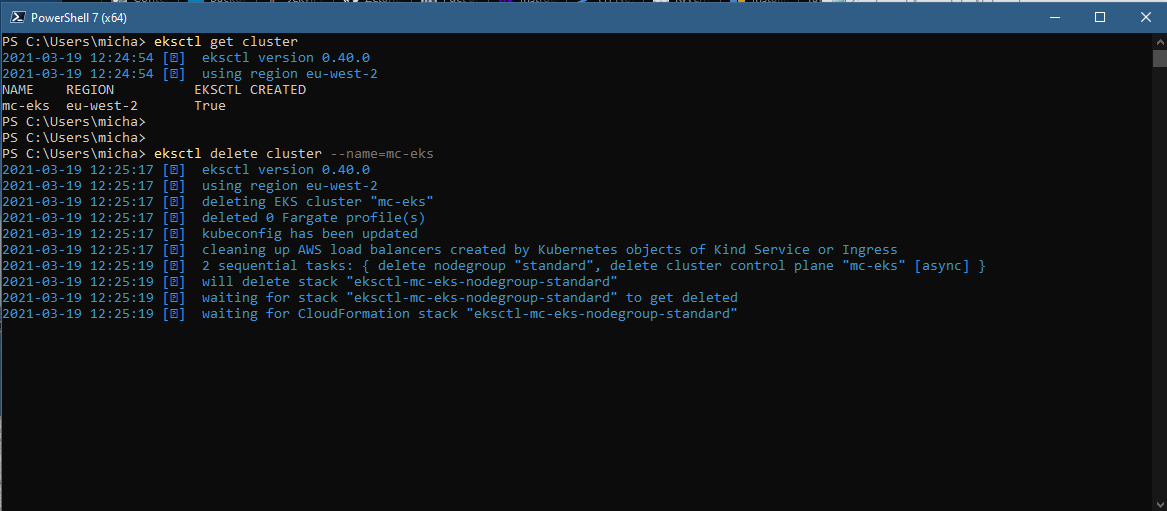
The final thing to note is, obviously this is costing you money whilst this is running so my advice is to get quick at deploying and destroying this cluster, use it for what you want and need to learn and then destroy it. This is why I still have a Kubernetes cluster available at home that costs me nothing other than it is available to me.
Hopefully, this will be useful to someone, as always open for feedback and if I am doing something not quite right then I am fine also to be educated and open to the community to help us all learn.
]]>The use case we are talking about is the ability to recover your backups from maybe on premises up into Microsoft Azure.
I was asked “what about AWS?” and yes of course if you are using the capacity tier option within Veeam Backup & Replication on premises and you are using the copy mode function to land a copy of your backups on AWS S3 or IBM Cloud or any S3 Compatible storage then there could be possible synergies in doing this in AWS, why I chose Microsoft Azure was simply because there is an Azure Marketplace offering we can take advantage of.
If you would like to see a similar series with AWS then let me know either on twitter or in the comments below. This will involve a different way of automating the provisioning of a Windows OS and the installation of Veeam Backup & Replication, but not too hard as we already have this functionality using Terraform & CHEF but only for vSphere but the code can be changed to work with AWS and really any platform that requires this functionality.
Veeam Configuration
As I said if you followed Part 1 of this series then you will have your Veeam server now running in Azure with no Veeam configuration.
In order for us to automate the direct restore process we need to provide some details in the script which i will share in stages and in full at the end of the post. But as a high level we need to
Add Azure Storage Account
Import Backups
Add Azure Compute Account
Then we will take those backups and run the Direct Restore to Microsoft Azure on the appropriate backups in a converted state ready to be powered on, or you can choose to power them on as part of this script process.
Firstly we need to add the Veeam snap in and connect to the local Veeam Backup & Replication Server, depending on where you run this script you will need to change the appropriate localhost below to the relevant DNS or IP Address. It is my recommendation that this is done on the server itself, but I am exploring how this PowerShell script could be hosted on your network and not publicly and used that way to fill in the secure details.
Add-PSSnapin VeeamPSSnapin


#Connects to Veeam backup server.

Connect-VBRServer -server "localhost"
Next we will add the Microsoft Azure Compute Account, this command will prompt you to login and authenticate into Microsoft Azure. I use MFA so this was the only way I could find to achieve this.
#Add Azure Compute Account


Add-VBRAzureAccount -Region Global
Next we will add the storage account, You will need to update the script with the requirements below.
Access Key – this will be based on a storage account that you have already created and you will need the long access key for authentication.
Azure Blob Account – this is the name of the storage blob account you have previously created. This is the same blob account and process that you used for adding Microsoft Azure Blob Storage to Veeam Backup & Replication on premises.
#Add Azure Storage Account


$accesskey = "ADD AZURE ACCESS KEY"


$blob1 = Add-VBRAzureBlobAccount -Name "AZUREBLOBACCOUT" -SharedKey $accesskey
Now we need to add our capacity tier, this is where you have been sending those backups.
#Add Capacity Tier (Microsoft Azure Blob Storage) Repository


$account = Get-VBRAzureBlobAccount -Name "AZUREBLOBACCOUNT"


$connect = Connect-VBRAzureBlobService -Account $account -RegionType Global -ServiceType CapacityTier


$container = Get-VBRAzureBlobContainer -Connection $connect | where {$_.name -eq 'AZURECONTAINER'}


$folder = Get-VBRAzureBlobFolder -Container $container -Connection $connect
The next part to adding capacity tier is important and I have also added this into the script, this repository needs to be added with exactly the same name that you have in your production Veeam Backup & Replication.
#The name needs to be exactly the same as you find in your production Veeam Backup & Replication server

$repositoryname = "REPOSITORYNAME"


Add-VBRAzureBlobRepository -AzureBlobFolder $folder -Connection $connect -Name $repositoryname
Next we need to import and rescan those backups that are in the Azure Blob Storage.
#Import backups from Capacity Tier Repository


$repository = Get-VBRObjectStorageRepository -Name $repositoryname


Mount-VBRObjectStorageRepository -Repository $repository

Rescan-VBREntity -AllRepositories
Now if you are using encryption then you will need the following commands instead of the one above.
#if you have used an encryption key then configure this section


$key = Get-VBREncryptionKey -Description "Object Storage Key"

Mount-VBRObjectStorageRepository -Repository $repository -EncryptionKey $key
At this point if we were to jump into the Veeam Backup & Replication console we would see our Storage and Compute accounts added to the Cloud Credential Manager, we would see the Microsoft Azure Blob Storage container added to our backup repositories and on the home screen you will see the object storage (imported) which is where you will also see the bakcups that reside there.
Next we need to create the variables in order to start our Direct Restore scenarios to Microsoft Azure.
A lot of the variables are quite self explanatory, but as a brief overview you will need to change the following to suit your backups.
VMBACKUPNAME = Which VM is it you want to restore
AZURECOMPUTEACCOUNT = this is the Azure Compute Account you added to Veeam Backup & Replication at the beginning of the script.
SUBSCRIPTIONNAME = you may have multiple subscriptions on one Azure compute account pick the appropriate one here.
STORAGEACCOUNTFORRESTOREDMACHINE = we are going to be converting that backup to your Azure Storage Group
REGION = Which Azure region would you like this to be restored to
$vmsize = this is where you will define what size Azure VM you wish to use here. In this example Basic_A0 is being used, you can change this to suit your workload.
AZURENETWORK = define the Azure Virtual Network you wish this converted machine to live.
SUBNET = Which subnet should the machine live
AZURERESOURCEGROUP = the Azure Resource Group you wish the VM to live
NAMEFORRESTOREDMACHINEINAZURE = Maybe a different naming conversion but this is what you wish to call your machine in Azure.
 #This next section will enable you to automate the Direct Restore to Microsoft Azure


$restorepoint = Get-VBRRestorePoint -Name "VMBACKUPNAME" | Sort-Object $_.creationtime -Descending | Select -First 1


$account = Get-VBRAzureAccount -Type ResourceManager -Name "AZURECOMPUTEACCOUNT"


$subscription = Get-VBRAzureSubscription -Account $account -name "SUBSCRIPTIONNAME"


$storageaccount = Get-VBRAzureStorageAccount -Subscription $subscription -Name "STORAGEACCOUNTFORRESTOREDMACHINE"


$location = Get-VBRAzureLocation -Subscription $subscription -Name "REGION"


$vmsize = Get-VBRAzureVMSize -Subscription $subscription -Location $location -Name Basic_A0


$network = Get-VBRAzureVirtualNetwork -Subscription $subscription -Name "AZURENETWORK"


$subnet = Get-VBRAzureVirtualNetworkSubnet -Network $network -Name "SUBNET"


$resourcegroup = Get-VBRAzureResourceGroup -Subscription $subscription -Name "AZURERESOURCEGROUP"


$RestoredVMName1 = "NAMEOFRESTOREDMACHINEINAZURE"
Now we have everything added to Veeam Backup & Replication, We have all the variables for our machines that we wish to convert and recover to Microsoft Azure VMs. Next is to start the restore process.
Start-VBRVMRestoreToAzure -RestorePoint $restorepoint -Subscription $subscription -StorageAccount $storageaccount -VmSize $vmsize -VirtualNetwork $network -VirtualSubnet $subnet -ResourceGroup $resourcegroup -VmName $RestoredVMName1 -Reason "Automated DR to the Cloud Testing"
The full script can be found here
#This script will automate the configuration steps of adding the following steps

#Add Azure Compute Account

#Add Azure Storage Account

#Add Capacity Tier (Microsoft Azure Blob Storage) Repository

#Import backups from Capacity Tier Repository

#This will then enable you to perform Direct Restore to Azure the image based backups you require.


Add-PSSnapin VeeamPSSnapin


#Connects to Veeam backup server.

Connect-VBRServer -server "localhost"


#Add Azure Compute Account


#Need to think of a better way to run this as this will close down PowerShell when installing

msiexec.exe /I "C:\Program Files\Veeam\Backup and Replication\Console\azure-powershell.5.1.1.msi"


Add-VBRAzureAccount -Region Global


#Add Azure Storage Account


$accesskey = "ADD AZURE ACCESS KEY"


$blob1 = Add-VBRAzureBlobAccount -Name "AZUREBLOBACCOUT" -SharedKey $accesskey


#Add Capacity Tier (Microsoft Azure Blob Storage) Repository


$account = Get-VBRAzureBlobAccount -Name "AZUREBLOBACCOUNT"


$connect = Connect-VBRAzureBlobService -Account $account -RegionType Global -ServiceType CapacityTier


$container = Get-VBRAzureBlobContainer -Connection $connect | where {$_.name -eq 'AZURECONTAINER'}


$folder = Get-VBRAzureBlobFolder -Container $container -Connection $connect


#The name needs to be exactly the same as you find in your production Veeam Backup & Replication server

$repositoryname = "REPOSITORYNAME"


Add-VBRAzureBlobRepository -AzureBlobFolder $folder -Connection $connect -Name $repositoryname


#Import backups from Capacity Tier Repository


$repository = Get-VBRObjectStorageRepository -Name $repositoryname


Mount-VBRObjectStorageRepository -Repository $repository

Rescan-VBREntity -AllRepositories


#if you have used an encryption key then configure this section


#$key = Get-VBREncryptionKey -Description "Object Storage Key"

#Mount-VBRObjectStorageRepository -Repository $repository -EncryptionKey $key


 #This next section will enable you to automate the Direct Restore to Microsoft Azure


$restorepoint = Get-VBRRestorePoint -Name "VMBACKUPNAME" | Sort-Object $_.creationtime -Descending | Select -First 1


$account = Get-VBRAzureAccount -Type ResourceManager -Name "AZURECOMPUTEACCOUNT"


$subscription = Get-VBRAzureSubscription -Account $account -name "SUBSCRIPTIONNAME"


$storageaccount = Get-VBRAzureStorageAccount -Subscription $subscription -Name "STORAGEACCOUNTFORRESTOREDMACHINE"


$location = Get-VBRAzureLocation -Subscription $subscription -Name "REGION"


$vmsize = Get-VBRAzureVMSize -Subscription $subscription -Location $location -Name Basic_A0


$network = Get-VBRAzureVirtualNetwork -Subscription $subscription -Name "AZURENETWORK"


$subnet = Get-VBRAzureVirtualNetworkSubnet -Network $network -Name "SUBNET"


$resourcegroup = Get-VBRAzureResourceGroup -Subscription $subscription -Name "AZURERESOURCEGROUP"


$RestoredVMName1 = "NAMEOFRESTOREDMACHINEINAZURE"


Start-VBRVMRestoreToAzure -RestorePoint $restorepoint -Subscription $subscription -StorageAccount $storageaccount -VmSize $vmsize -VirtualNetwork $network -VirtualSubnet $subnet -ResourceGroup $resourcegroup -VmName $RestoredVMName1 -Reason "Automated DR to the Cloud Testing"
Feedback is key on this one and would love to make this work better and faster. Feedback welcome below in the comments as well as getting hold of me on Twitter.
]]>Installing Azure PowerShell
In order for us to start this automated deployment we need to install locally on our machine the Azure PowerShell module.
More details of that can be found here.
Run the following code on your system.
if ($PSVersionTable.PSEdition -eq 'Desktop' -and (Get-Module -Name AzureRM -ListAvailable)) {

    Write-Warning -Message ('Az module not installed. Having both the AzureRM and ' +

      'Az modules installed at the same time is not supported.')

} else {

    Install-Module -Name Az -AllowClobber -Scope CurrentUser
Select either [Y] Yes or [A] Yes to All as this is an untrusted repository. You can also change currentuser to allusers if you wish to enable for all users on the local machine.
Breaking down the code
This section is going to talk through the steps taken in the code, the way in which this will work though is by taking this code from the GitHub Repository you will be able to modify the variables and begin testing yourself without any actual code changes.
First we need to connect to our Azure account, this will provide you with a web browser to login to your Azure Portal, if you are using MFA then this will enable you to authenticate this way also.
# Connect to Azure with a browser sign in token

Connect-AzAccount
Next we want to start defining what, where and how we want this to look in our Azure accounts. It should be pretty straight forward to understand the following but
locName = Azure Location
Publisher Name = Veeam
Offer Name = is the particular offering we wish to deploy from the publisher, there are quite a few so expect to see other options using this method.
SkuName = what product sku of the offering do you wish to use
version = what version of the product
# Set the Marketplace image

$locName="EASTUS"

$pubName="veeam"

$offerName="veeam-backup-replication"

$skuName="veeam-backup-replication-v10"

$version = "10.0.1"
The following are aligned to the environment.
resourcegroup = which resource group do you wish to use this can be an existing resource group or a new name
vmname = what name do you wish your Veeam Backup & Replication server to have within your Azure environment
vmsize = this is the image that will be used, my advice to pick the supported sizes, this is the default size used for production environments.
# Variables for common values

$resourceGroup = "CadeTestingVBR"

$vmName = "CadeVBR"

$vmSize = "Standard_F4s_v2"
Next we need to agree to the license terms of deploying from the marketplace for this specific VM Image. The following commands will do this.
Get-AzVMImage -Location $locName -PublisherName $pubName -Offer $offerName -Skus $skuName -Version $version


$agreementTerms=Get-AzMarketplaceterms -Publisher "veeam" -Product "veeam-backup-replication" -Name "10.0.1"


Set-AzMarketplaceTerms -Publisher "veeam" -Product "veeam-backup-replication" -Name "10.0.1" -Terms $agreementTerms -Accept
If you wish to review the terms then you can do by running the following command. Spoiler alert the command will give you a link to a txt file to save you the hassle here is the link in the txt file where you will find the Veeam EULA – https://www.veeam.com/eula.html
Get-AzMarketplaceTerms -Publisher "veeam" -Product "veeam-backup-replication" -Name "10.0.1"
Next we need to start defining how our Veeam Backup & Replication server will look in regards to configuration of network, authentication and security.
I also wanted to keep this script following best practice and not containing any usernames or passwords so the first config setting is to gather the username and password for your deployed machine in a secure string.
# Create user object

$cred = Get-Credential -Message "Enter a username and password for the virtual machine."
Create a resource group
# Create a resource group


New-AzResourceGroup -Name $resourceGroup -Location $locname -force
Create a subnet configuration
# Create a subnet configuration

$subnetConfig = New-AzVirtualNetworkSubnetConfig -Name "cadesubvbr" -AddressPrefix 10.0.0.0/24
Create a virtual network
# Create a virtual network

$vnet = New-AzVirtualNetwork -ResourceGroupName $resourceGroup -Location $locName `

  -Name CadeVBRNet -AddressPrefix 10.0.0.0/24 -Subnet $subnetConfig
Create a public IP Address
# Create a public IP address and specify a DNS name

$pip = New-AzPublicIpAddress -ResourceGroupName $resourceGroup -Location $locName `

  -Name "CadeVBR$(Get-Random)" -AllocationMethod Static -IdleTimeoutInMinutes 4
Create inbound security group rule for RDP
# Create an inbound network security group rule for port 3389

$nsgRuleRDP = New-AzNetworkSecurityRuleConfig -Name CadeVBRSecurityGroupRuleRDP  -Protocol Tcp `

  -Direction Inbound -Priority 1000 -SourceAddressPrefix * -SourcePortRange * -DestinationAddressPrefix * `

  -DestinationPortRange 3389 -Access Allow
Create network security group
# Create a network security group

$nsg = New-AzNetworkSecurityGroup -ResourceGroupName $resourceGroup -Location $locName `

  -Name CadeVBRNetSecurityGroup -SecurityRules $nsgRuleRDP
Create a virtual network
# Create a virtual network card and associate with public IP address and NSG

$nic = New-AzNetworkInterface -Name CadeVBRNIC -ResourceGroupName $resourceGroup -Location $locName `

  -SubnetId $vnet.Subnets[0].Id -PublicIpAddressId $pip.Id -NetworkSecurityGroupId $nsg.Id
Next we need to define what the virtual machine configuration is going to look in our environment using the above environment configurations.
#Create a virtual machine configuration


$vmConfig = New-AzVMConfig -VMName "$vmName" -VMSize $vmSize

$vmConfig = Set-AzVMPlan -VM $vmConfig -Publisher $pubName -Product $offerName -Name $skuName

$vmConfig = Set-AzVMOperatingSystem -Windows -VM $vmConfig -ComputerName $vmName -Credential $cred

$vmConfig = Set-AzVMSourceImage -VM $vmConfig -PublisherName $pubName -Offer $offerName -Skus $skuName -Version $version

$vmConfig = Add-AzVMNetworkInterface -Id $nic.Id -VM $vmConfig
Then now we have everything we need we can now begin deploying the machine.
# Create a virtual machine

New-AzVM -ResourceGroupName $resourceGroup -Location $locName -VM $vmConfig
If you saw the video demo you would have seen that the deployment really does not take long at all, I actually think using this method is a little faster either way less than 5 minutes to quickly deploy a Veeam Backup & Replication server in Microsoft Azure.
Now that we have our machine there is one thing we want to do to ensure the next stages of configuration run smoothly. Out of the box there is a requirement for Azure PowerShell to be installed to be able to use the Azure Compute accounts and Direct Restore to Microsoft Azure. The installer is already on the deployed box and if we go through manually you would have to just install that msi instead in this script we remote run a powershell script from GitHub that will do it for you.
# Start Script installation of Azure PowerShell requirement for adding Azure Compute Account

Set-AzVMCustomScriptExtension -ResourceGroupName $resourceGroup `

    -VMName $vmName `

    -Location $locName `

    -FileUri https://raw.githubusercontent.com/MichaelCade/veeamdr/master/AzurePowerShellInstaller.ps1 `

    -Run 'AzurePowerShellInstaller.ps1' `

    -Name DemoScriptExtension
At this stage the PowerShell installation for me has required a reboot but it is very fast and generally up within 10-15 seconds. So we run the following command to pause the command before then understanding what that public IP is and then start a Windows Remote Desktop to that IP address.
Start-Sleep -s 15


Write-host "Your public IP address is $($pip.IpAddress)"

mstsc /v:$($pip.IpAddress)
Now, this might seem like a long winded approach to getting something up and running but with this combined into one script and you having the ability to create all of this on demand brings a powerful story to being able to recover workloads into Microsoft Azure.
In the next parts to this post will concentrate on a configuration script which is where we will configure Veeam Backup & Replication to attach the Microsoft Azure Blob Storage where our backups reside, Our Azure Compute Account and then we can look at how we could automate end to end this process to bring your machines up in Microsoft Azure when you need them or before you need them.
here is the complete script
# Connect to Azure with a browser sign in token

Connect-AzAccount


# Set the Marketplace image

$locName="EASTUS"

$pubName="veeam"

$offerName="veeam-backup-replication"

$skuName="veeam-backup-replication-v10"

$version = "10.0.1"


# Variables for common values

$resourceGroup = "CadeTestingVBR"

$vmName = "CadeVBR"

$vmSize = "Standard_F4s_v2"

$StorageSku = "Premium_LRS"

$StorageName = "cadestorage"


Get-AzVMImage -Location $locName -PublisherName $pubName -Offer $offerName -Skus $skuName -Version $version


$agreementTerms=Get-AzMarketplaceterms -Publisher "veeam" -Product "veeam-backup-replication" -Name "10.0.1"


Set-AzMarketplaceTerms -Publisher "veeam" -Product "veeam-backup-replication" -Name "10.0.1" -Terms $agreementTerms -Accept


# Create user object

$cred = Get-Credential -Message "Enter a username and password for the virtual machine."


# Create a resource group


New-AzResourceGroup -Name $resourceGroup -Location $locname -force


# Create a subnet configuration

$subnetConfig = New-AzVirtualNetworkSubnetConfig -Name "cadesubvbr" -AddressPrefix 10.0.0.0/24


# Create a virtual network

$vnet = New-AzVirtualNetwork -ResourceGroupName $resourceGroup -Location $locName `

  -Name CadeVBRNet -AddressPrefix 10.0.0.0/24 -Subnet $subnetConfig


# Create a public IP address and specify a DNS name

$pip = New-AzPublicIpAddress -ResourceGroupName $resourceGroup -Location $locName `

  -Name "CadeVBR$(Get-Random)" -AllocationMethod Static -IdleTimeoutInMinutes 4


# Create an inbound network security group rule for port 3389

$nsgRuleRDP = New-AzNetworkSecurityRuleConfig -Name CadeVBRSecurityGroupRuleRDP  -Protocol Tcp `

  -Direction Inbound -Priority 1000 -SourceAddressPrefix * -SourcePortRange * -DestinationAddressPrefix * `

  -DestinationPortRange 3389 -Access Allow


# Create a network security group

$nsg = New-AzNetworkSecurityGroup -ResourceGroupName $resourceGroup -Location $locName `

  -Name CadeVBRNetSecurityGroup -SecurityRules $nsgRuleRDP


# Create a virtual network card and associate with public IP address and NSG

$nic = New-AzNetworkInterface -Name CadeVBRNIC -ResourceGroupName $resourceGroup -Location $locName `

  -SubnetId $vnet.Subnets[0].Id -PublicIpAddressId $pip.Id -NetworkSecurityGroupId $nsg.Id


# Create a virtual machine configuration

#vmConfig = New-AzVMConfig -VMName $vmName -VMSize $vmSize | `

#Set-AzVMOperatingSystem -Windows -ComputerName $vmName -Credential $cred | `

#Set-AzVMSourceImage -VM $vmConfig -PublisherName $pubName -Offer $offerName -Skus $skuName -Version $version | `

#Add-AzVMNetworkInterface -Id $nic.Id


#Create a virtual machine configuration


$vmConfig = New-AzVMConfig -VMName "$vmName" -VMSize $vmSize

$vmConfig = Set-AzVMPlan -VM $vmConfig -Publisher $pubName -Product $offerName -Name $skuName

$vmConfig = Set-AzVMOperatingSystem -Windows -VM $vmConfig -ComputerName $vmName -Credential $cred

$vmConfig = Set-AzVMSourceImage -VM $vmConfig -PublisherName $pubName -Offer $offerName -Skus $skuName -Version $version

$vmConfig = Add-AzVMNetworkInterface -Id $nic.Id -VM $vmConfig


# Create a virtual machine

New-AzVM -ResourceGroupName $resourceGroup -Location $locName -VM $vmConfig


# Start Script installation of Azure PowerShell requirement for adding Azure Compute Account

Set-AzVMCustomScriptExtension -ResourceGroupName $resourceGroup `

    -VMName $vmName `

    -Location $locName `

    -FileUri https://raw.githubusercontent.com/MichaelCade/veeamdr/master/AzurePowerShellInstaller.ps1 `

    -Run 'AzurePowerShellInstaller.ps1' `

    -Name DemoScriptExtension


Start-Sleep -s 15


Write-host "Your public IP address is $($pip.IpAddress)"

mstsc /v:$($pip.IpAddress)
You can also find this version and updated versions of this script here in my GitHub repository.
Any comments feedback either down below here, twitter or on GitHub.
]]>I think with the options we have available today to store our personal data and our mission critical enterprise data and everything in between we have so much choice.
This session was focused on how the cloud could help when it comes to storing your data in Microsoft Azure.
Three key things that the session enabled viewers to go away with were.
- Understand the type of data you have
- Azure has hosted options for databases
- Your data solution should be able to grow with you
What is important for you – the customer
There are thousands of things that will be specific, but many will be very similar.
- How can we make things faster?
- Limit or mitigate risk when deploying new services
- Putting more control to the developers in the organisation
- Scalability
- Using the right tool for the job and potentially being able to pivot when need be
Should we have a storage strategy?
The session moved into more of a why is a storage strategy important. This has been something a good friend of mine Paul Stringfellow has been speaking about both on his blogs and his podcasts, and this relates to all customers not just large enterprise customers and environments should have a storage or data strategy.
We should always be considering,
- Maintaining Security
- Breaking down data and storage services into manageable set
- Consider the lifespan of the data and where it needs to be and for how long?
Before we start
What data do you have?
- Structured Data – data that has been organised into a formatted repository, typically a database, so that its elements can be made addressable for more effective processing and analysis. A data structure is a kind of repository that organizes information for that purpose.
- Unstructured Data – information that either does not have a pre-defined data model or is not organized in a pre-defined manner. Unstructured information is typically text-heavy, but may contain data such as dates, numbers, and facts as well.
- Semi Structured Data – a form of structured data that does not obey the formal structure of data models associated with relational databases or other forms of data tables, but nonetheless contains tags or other markers to separate semantic elements and enforce hierarchies of records and fields within the data.
How much data do you have?
- Volume
- Variety
- Velocity
Azure Storage Services
There is quite the storage offering when it comes to Microsoft Azure and it’s important to understand the options for those data types and what should be stored where.

What is Azure Blob Storage?
Azure’s Object Storage platform used to store and serve unstructured data.
- App and Web scale data
- Backups and Archive
- Big Data from IoT, Genomics, etc.
My interest here instantly went toward the backup mention above and in particular how Veeam have been leveraging Object Storage for backup data across the platform for storing the backup formats for either long term retention, direct copies but also copies of your Microsoft Office 365 backup data. Some of the characteristics that come with object storage especially with Microsoft Azure Blob Storage.
- Infinite scale
- Globally accessible
- Cost efficient
Databases – Relational Databases
Relational databases have many different options within Microsoft Azure.
The first option is by taking your on-premises SQL or relational database and migrating those VMs or workloads to Microsoft Azure. But this is likely not going to be the best route to take because of cost and management.
The compelling route should be more along the line of PaaS offerings from Azure, these could be any of the following and I am sure there a likely new services happening as and when the demand is great enough.
- Azure SQL Database
- SQL Data Warehouse
- PostgreSQL
- MySQL
- MariaDB
All of these PaaS offerings still leverage the Azure Compute and Storage layer, but they offer the ability for many other Azure services to work with these databases.
Cosmos DB
Azure Cosmos DB – A globally distributed, massively scalable, multi-model database service
A NoSQL database is different to what we just mentioned with SQL or other relational databases.

I actually want to learn some more about Azure Cosmos DB, the introduction in this session was great and opened my eyes to this actually being not another flavour of a NoSQL database but potentially an aggregation of existing NoSQL databases. I need to learn more on this for another time.
I am really interested in the distributed format of these databases and the ease of use about being able to have a write region and then additional read regions across the world or at least in different locations. However, you can have multi region writes which will help with scale.
Resources
All of this is really well covered in the Azure Documentation – https://aka.ms/apps20ignite
Another thing that I had to share was the learning paths for this session alone. Almost 15 hours of training! This is hands on training and interactive without the billing but all the learning!
]]>A big focus on
- Containers & Kubernetes
- Public Cloud Hyperscalers (Microsoft Azure, AWS and Google Cloud Platform)
- Infrastructure as Code & Automation
My aim for the public cloud and in particular Microsoft Azure was to get a better understanding on why? Why would some of our existing customers want or should they move to Microsoft Azure and what options do they have in doing so?
The level of education I am aiming for is around foundation learning curve that allows me to better understand in all three of the fore mentioned public cloud hyperscalers
- Compute
- Storage
- Security
- Networking
The idea is not to sit all the certifications and become a master in any or all that would be insane, but an understanding is required to be able to have those conversations in the field with our customers and prospects.
My Azure learning started with the Ignite sessions all available online. I have to say Microsoft really do nail the production quality and the time to get this stuff online straight after they have happened. It was the first ignite on tour or at least the one in London that got me interested and although I could not attend the live show, I was able to grab the agenda.
This first write up will touch on the “Getting Started” and will focus on the session that was delivered by Frank Boucher called “Options for Building and Running Your App in the Cloud” The session touches on the options available and security as the first steps of understanding and leveraging the public cloud for what it was built for.
Franks first comment and I think this is a solid way of thinking about cloud technologies. There are no bad choices… there is no bad first step. But I will add to this the purpose and the requirement of that data and use case has to be clear. If the data is important make sure it is protected against failure.
There are always plenty of options, just get started and you can always or should always be able to move to other options or find better ways to improve your application or the purpose you are trying to achieve.
Deployment Tools
Visual Studio IDE
Modular, QA / Test very versatile and regardless of your programming language there are options. Multi-platform and also in the cloud version. Visual Studio Online
- Multi-Platform (Windows & Mac)
- Customisable workloads
- Multi-Language
- Tons of Extensions
- Live Share – Real time collaborative development!
Visual Studio Code
Lighter version of the previously mentioned IDE version. Less features but still powerful,
- GIT commands built in
- extensible and customisable
- Full support for all platforms (Linux, Mac and Windows)
Terminal & CLI
- Cloud Shell
- Azure CLI
- Azure PowerShell
ARM Templates
Azure Resource Manager Template, this is where we meet infrastructure as code functionality where we concentrate on version control, a fast way to deploy resources in a declarative model without having to manually deploy our infrastructure.
- Architecture / Infrastructure as code
- Version Control
- Fastest Way to deploy
ARM templates might be a completely new way of looking for many infrastructure administrators, but I have to say the Microsoft Documentation in this area is amazing.
Deployment options
Now we know some of the tools available and there are others but I wanted to focus on the Microsoft options, I personally believe that at this point there is a strong focus on using especially when it comes to Infrastructure as code, You may want to be agnostic to where you run your deployment, for this something like Terraform from HashiCorp is a great option to achieve this across multiple platforms.
Let’s take a website as the example of what we want to consider deploying. There are many options available.
Azure Blob Static Websites
- Very low cost – Cheapest option
- Fast
- Static – however although this can be HTML it can also be more complexed options using Angular and React
PaaS (Web Apps)
PaaS removed the requirement to manage the architecture at a deep level, Scaling, Backup, Disaster Recovery and other platform tasks that are now managed by the service.
- Client Side & Server Side
- PaaS Features
- Windows & Linux
- Many Languages Supported (.NET, Java, PHP, Ruby, Python… etc.)
Containers
A couple of container options when it comes to Azure
- ACI – Azure Container Instance
- AKS – Azure Kubernetes Services
There are many different use cases between the two offerings above but also some overlap. I am not going to get into the AKS or Kubernetes in general benefits and functionality but if you are looking to simply run a very small or very simple application or service then ACI is going to be a great choice there. If you require scale and deeper choices and orchestration for your containers, then AKS will be the likely choice.
Virtual Machines
What if you already have the web server already configured and working in a different location, maybe on premises for example running in VMware as a virtual machine. You don’t have time to change this, but you want to get to Azure and that’s also possible.
Veeam has the ability in the free version to Directly restore image-based backups to Azure.
Shared Image Gallery
There is also a gallery that contains different images available, different Operating Systems and versions for both Windows & Linux. Some of these images also contain application deployments also.
- Databases
- Web Servers
- Development Tools
Basic Security Features
Security has to be at this stage of the project, it should not be an afterthought. Because you may start and you are the only developer / operations engineer but then you scale out and out and out. Meaning sharing security keys and passwords over messenger apps becomes a complete vulnerability in your process.
Azure Key Vault
Azure Key Vault is a cloud service for safeguarding encryption keys and application secrets for your cloud applications.
The AKV keeps or focuses on clear separation of security duties, meaning that the role attributed to security can be in charge and manage the important security aspects.
- Encryption Keys
- Secrets
- Certificates
Whilst App owners can consume and use the certificates in their applications. As well as your deployment being secured and segregated.
- Manage all of your secrets in one place
- Seamlessly move between Development, QA, and Production environments
- Update credentials in one spot and update everyone’s credentials
- Version, enable, and disable credentials as needed
- Add a credential and it’s instantly available to all Developers in a controlled manner
Managed Service Identity (MSI)
Ok, so Azure Key Vault sounds great but how do we get into it to control the security aspects that have just been mentioned. How do we authenticate into AKV?
So we need credentials to get credentials…
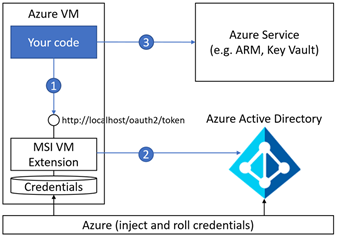
Your deployment is registered with Azure this can be that VM, Function or anything we mentioned in that above Deployment Options. A local endpoint is exposed but this is only accessible within your local host that allows for access to valid credentials within the key vault.
Loads more reading material at aka.ms/docAAD on Azure Active Directory.
Resources
]]>As I said above, I wanted to get into some of the examples of actually some of the tools used to provision your infrastructure using code, terraform use the terms “Execution Plans” to describe the way your code is deployed.
Terraform was created by a company called Hashicop they have a number of really good tools in this space.
The biggest pull factor for me and why I wanted to kick things off with Terraform is because Terraform is cloud agnostic or pretty much any infrastructure agnostic as you can use Terraform with you on premises vSphere environment as well as AWS, Azure and GCP Cloud Platforms. Below is a link to an awesome but simple introduction to Terraform. All of these resources can be found here amongst other training material around other tools available.
Azure Resource Manager Templates
Up until today I would have put the ability of using PowerShell in Azure to deploy my Resource Groups and Storage Accounts was IAC. I was wrong, the code itself could form some of that IAC effort but alone in a PowerShell script this is not IAC.
IAC in an Azure world is determined around Azure Resource Templates. A Declarative way of saying this is how I want the end state to be within my Azure environment. These are defined in a JSON file and they allow you to determine how and what your resource and infrastructure looks like.
These templates can be deployed through PowerShell, Azure CLI or through the Azure console.
The biggest thing that needs to happen here and the benefit of IAC is understanding and being able to use versioning, a good example of versioning would be using GIT this allows for source control so you can see when things have changed to the configuration code.
There are alternatives to GIT but I am pretty confident as a noob here that GIT is the mostly used out there, and really I am not looking to be a programmer I just need to understand and potentially be able to act upon a little but not be a fully-fledged and knighted into the Developer kingdom.
Azure DevOps is another resource to mention here. Azure DevOps allows for your developers to collaborate on code development, again this could be a little outside the IAC remit, but there may be some use cases where it is absolutely required as part of IAC.
Azure Repos are leveraged to centrally store code but there are a lot of other Azure services that coexist in here and potentially worth reading some more here if interested.
What was interesting in the resource video stated below “Infrastructure as code for the IT administrator” the presenter also touches on Continuous Deployment and Azure Pipelines. I found this very interesting in that by pushing changes to GIT it would automatically deploy those committed changes to the pipeline or workflow.
I think the example that John Savill uses in the demo is very simple and to be honest that task could be quicker using the UI but obviously he didn’t have endless amounts of time to walk through a more aligned example of this but I think it is the best resource I have seen today where it explains what IAC is and why it should be absolutely considered.
AWS CloudFormation
I think by now we are clear that Infrastructure As Code is about yes code but it’s probably more important to remember that it’s about version control and a Declarative way of saying this is how I want the end state to be within my environment, whichever environment you wish that to be.
Now a question I have at this point is we first talked about Terraform and we stated how it was agnostic to the environment it can be used with vSphere, AWS, Azure etc etc now colour me silly but am I right in thinking that Azure Resource Templates mentioned in the last section and AWS CloudFormation are fixed to their public cloud offerings?
This is quite an old resource but this completely makes sense to me – https://www.techdiction.com/2017/08/24/migrating-aws-cloudformation-templates-to-azure-resource-manager-templates/
I am still convinced that maybe Terraform is the right fit but I might be missing something fundamental here.
In the same way I mentioned in the Azure section and the nature of templates. AWS Cloud Formations use templates also which is a JSON file.
That JSON file serves as a blueprint to define the configuration of all the AWS resources that make up your infrastructure and application stack or you can select a sample pre-built templates that CloudFormation provides for commonly used architectures such as a lamp stack running on Amazon ec2 and Amazon RDS.
Upload your template to CloudFormation, select parameters such as the number of instances or instance types if necessary then CloudFormation will provision and configure your AWS resource stack.
Update your CloudFormation stack at any time by uploading a modified template through the AWS management console or command line.
You can check your template into version control so it’s possible to keep track of all changes made to your infrastructure and application stack.
CloudFormation brings the ability to leverage version control your infrastructure architecture the same way you would with software code.
Provisioning infrastructure seems as simple as creating and uploading a template to CloudFormation.
My first thought here now that I have touched on 3 of the most commonly used IAC tools in the industry today is that whichever one you use this makes it very simple and easy to replicate your infrastructure again and again either for additional site rollouts or test and development scenarios.
The ability to easily and quickly spin up a replica of your production environment for development and test with just a few clicks in this case the AWS management console and then quickly tear it down when finished and rebuild and rinse and repeat that process whenever you want. Manually this was always going to be a pain point and although yes IAC is apparent today in the traditional on premises world it’s reliant on having the physical hardware in place to make this happen unless software or application stack only in which case that could work if resources were spare. In the Public Cloud with those infinite resources this is a great story to be told.
Google Cloud Deployment
Typically Google Cloud Platform is the one Public Cloud out of the above 2 already mentioned that I have not really had any dealings with at all, so when I come to look for resource on Google Cloud Deployment, there is very little out there, great from a content creation point of view if you know your way around the platform, rubbish if you are learning.
Although looking at the product page. It follows the same footprint as the above-mentioned tools but with a focus on the Google Cloud Platform.
- Simplify your cloud management
- Repeatable deployment process
- Declarative language
- Focus on the application
- Template-driven
One thing at first glance that I really like about Google is that they seem to have the documentation down really well and depending on how we get on this summer I think before we see the end of 2019 I want to be in better shape to understand more about GCP.
GIT
GIT is a version control system, open source, distributed architecture. The reason for the mention is that it may be required. Generally I get the impression that this is used on projects where you have multiple developers and you need some version control, I thought it was worth mentioning though as there will be some use cases within IAC where this will be relevant and matter to Infrastructure admins.
This is a great resource that will actually allow you to walk through some use cases with GIT
Resources
I cannot take any credit for this collection of resources either used above or below, these were all shared on the show notes of CloudSkills.fm I will also keep adding resources here as I find good useful content to share.
CloudSkills.fm – Infrastructure as code in the cloud:002
Build Azure Resource Manager templates
AWS CloudFormation Getting Started
Google Cloud Deployment Manager
Infrastructure as Code for the IT Administrator
I know this was a long post, but I think as a primer into each of the areas was enough and it didn’t seem long enough for each tool to have their own post. Also, you can probably tell that a lot of the content here is basically my notes. There is going to be a huge amount that I am sure I have missed but I wanted to get my views over on what I think or what I deem to be important as we move into this new world. Depending on time there is an endless amount of content, training and follow ups to go back to here and I really find this an interesting part of the future or as we move more and more into the Cloud Computing space.
]]>I felt that although I believe in the first post, I have grasped the reasons behind and the benefits for Infrastructure As Code I think we need to take a look how things were traditionally managed and still are for the most part in on premises datacentre. But also highlight some of the reasons why things are changing.
How was infrastructure traditionally managed
The Infrastructure was traditionally managed and still is today by many organisations, for example let’s take a common estate. VMware running inside of a private data center, the classic approach would be if I’m a consumer of infrastructure I would file a request and then someone at the other end of this request queue is pulling it off logging into either a management portal or an administrative console and pointing and clicking to provision that piece of infrastructure
There is no issue with this especially if I didn’t have to manage a lot of infrastructure or if the churn of my infrastructure was relatively minimal and this was and is true for many sort of private data centers, a Virtual Machine would live for months to years, there was a relatively limited scale of deployment and so it was possible to manually point and click and administer these systems.
Things are changing
There are a couple of changes that are changing the way we also think about the traditional sense of managing our infrastructure. The first of those changes is we do not just have that one private data center to administer we have a sprawl of other possible consumable cloud-based environments and with that they are API driven. The second change is around the elasticity of infrastructure where instead of months to years it’s now days to weeks in terms of how long a resource might live.
The scale of infrastructure is much higher because instead of a handful of large instances we might have many smaller instances there’s many more things we need to provision, and this infrastructure tends to be occurring in cycles and regularly repeating.
We might scale up to handle our load during peak days and times and scale down at night to save on cost because it’s not a fixed cost unlike owning hardware that we can depreciate we’re now paying by the hour, so it makes sense to only use the infrastructure you need and you have to have the sort of elasticity.
As you start making these changes all of a sudden the thought of I’m going to file a thousand requests every morning to spin up to our peak capacity and then file another thousand requests at night to spin back down and then manually manage all this is clearly going to become challenging in terms of how do we even begin to operationalise this in a way that’s reliable and robust and not prone to human error.
There is a change in terms of the dynamics of our infrastructure, the idea behind infrastructure as code is how do we take the process that we were pointing and clicking to achieve our end goal and capture that in a codified way and now if I need to that task one time, ten times or a thousand times I can automate that so now every morning I can run a script that brings up a thousand machines and every evening hit the same script to bring it back down to whatever the required footprint should be. We can begin to both automate that but also now that we have captured the code form, we can start versioning control, we can then see an incremental history of who changed what. This methodology also allows you to see how the infrastructure is actually defined at any given point of time and we have this transparency of documentation, that we don’t have in the traditional point-and-click environment.
The reusability of the code and the ability to then drive automation tasks whilst keeping version control is the real value of Infrastructure as code.
Next up is a long post covering some examples of Infrastructure As Code, in particular I have chosen Terraform from a Cloud agnostic approach, and then each of the major public cloud hyperscalers options to IAC.
]]>
First Steps
I also mentioned in the first post about some of the resources I was going to get into but this will take from those resources my own spin and take on what I learnt and hopefully somewhere out there it helps someone else, I will of course list my resources again at the end.
Initial Overview and Perspective
Having already played in this area a little for just over a year I think I have a pretty good understanding of what Infrastructure As Code is and what benefit it brings, but I also want to make sure I portray my thoughts here as well.
Infrastructure as code is the practice of defining your architecture formally in some form of code usually this looks like a set of templates that describe your architecture along with configuration files for setting parameters. The biggest reasons to use infrastructure as code are to save yourself repeated work and to know exactly what’s in the environment at any point in time. Your infrastructure will become more reliable repeatable and ephemeral by using infrastructure as code you can stand up environments so fast to play around in them and tear them back down to save costs.
When you use infrastructure as code it’s important to stick to using infrastructure as code once you describe something in the template all updates to it need to be made in that template otherwise you risk introducing drift of configuration.
Wikipedia the keeper of truth has a pretty good opener on what IAC is also.
“Infrastructure as code (IaC) is the process of managing and provisioning computer data centers through machine-readable definition files, rather than physical hardware configuration or interactive configuration tools.[1] The IT infrastructure managed by this comprises both physical equipment such as bare-metal servers as well as virtual machines and associated configuration resources. The definitions may be in a version control system. It can use either scripts or declarative definitions, rather than manual processes, but the term is more often used to promote declarative approaches.
IaC approaches are promoted for cloud computing, which is sometimes marketed as infrastructure as a service (IaaS). IaC supports IaaS but should not be confused with it.”
The three reasons I can see people moving this way towards Infrastructure As Code is basically down to Speed, Risk and it offering a highly efficient way of deploying infrastructure.
Speed – If you take a process and you can just copy and paste it then its effectively quicker than typing the line of code or performing the process over and over again IAC allows for that template methodology and how people can take advantage of templating their infrastructure or even applications.
Risk – If you leverage the template like function you are removing the amount of hands on interaction an actual human being needs to have with the infrastructure thus removing risk or at least some risk.
Efficiency – templating analogy again means I can repeat this process over and over again, hundreds and thousands of times and each time we are going to get the same output with the correct parameters and settings.
In the next posts, I am going to drill into some of the key areas that I have found to be most useful to understand and learn more on and I think as a follow up I will go into each one in more detail. In the next post up though I am going to look at the WHY IAC is a thing and how things were and why the needs to make this shift for both on premises and cloud computing.
There are a large number of offerings here and some that I didn’t touch on were the likes of vSphere vRealize Automation, Ansible, Puppet or CHEF all absolutely valid tools to provide IAC but I wanted to keep things broad and also show the Public Cloud native service offerings.
]]>This summer I felt it was now around the right time to use these slowly dwindling 3 weeks of summer before we head to VMworld to really focus in on some of the new “Cloud Computing” or “Cloud Native” areas that I have thus far only really brushed over and know enough to ask questions but very little to add input or ideas around.

Every one of us trains in different ways, some love to read, some love to watch and some love to listen and there are people that span all or some of those formats. For me the best form of training is watching and listening, training videos and podcasts are my go-to at least to start then its hands on and make something work. I am not a classroom fan, never have been… brings back too many memories of school, and reading is only good for getting to sleep. I will say though that I have found my happy medium when it comes to “reading” and that’s Audible, I have simply amazed myself with the number of books I have been through so far this year. Amazing for someone that only really read maybe a book a year.
Ok so you think you want to learn Cloud Native… where do you start. I don’t know.
The first resource I found through sharing and in fact I believe it was Nick Howell now Field CTO at NetApp for their Cloud Data Services Business Unit was the “CNCF Cloud Native Interactive Landscape” this my friends is a monster syllabus for learning Cloud Native!
At the time of writing this post there are 1,172 cards, this is a really good resource as this is the bible and is constantly updated.
The screen grab I took is barely visible, the landscape is vast and someone coming from an infrastructure point of view may be absolutely overwhelmed at first. I know I am and was even more so a few weeks back.

Where do you start?
Before you start you need to understand what the focus and end game is, for me my end game is to know more about these areas so that I can understand how and what pain points customers are having as they move into this new way of IT delivery.
I come from an Infrastructure point of view, I know Storage systems very well, I know virtualisation very well, backup and more recently I have let’s say dabbled into automation and configuration space.
For me looking at that above matrix of all these vendors of which some I have never heard of it was overwhelming, but when you actually look at the sections it became a lot clearer for me.
The first area I want to focus on is Infrastructure as code but on this chart really the focus is “Provisioning – Automation & Configuration” 72 cards in total of vendors again some of which I had never come across.
The reason for this choice is I know the infrastructure side of things and this section by all accounts allows me to take that infrastructure and automate the deployment and configuration of the different aspects.

Let’s work back one step
I mentioned that I know how I train and how I learn but before you get started on any personal project you need to make sure you know where or at least roughly where your education material is going to come from.
Over the last few years I have defaulted to checking Pluralsight first for video training, I am extremely lucky that as part of my #CiscoChampion and #vExpert membership I receive a rolling 12-month free subscription for the service. I would argue this is one of the most valuable perks of being in the advocacy programs. And if you don’t use it you absolutely should.

There is a course there that I fully intend to start with once I get through some podcasts on the same topic.
Infrastructure from Code: The Big Picture Now it is from 2017 so I don’t know if it’s going to throw things off to what we have today. But the premise of the course and overview is going to be a good primer and probably the level of education I need today.
My second pick for a resource of where I am going to get going is with this podcast that started at the very beginning of 2019 and it’s a weekly podcast so quite easy to get caught up moving forward. The podcast is CloudSkills.fm and is hosted by Mike Pfeiffer and listening to the opening show from January 2019 I was like well this is exactly where I am at.

The first show as I said was an introduction and touches on some of the certifications and training out there in this space. The second episode gives a good 30-minute primer on Infrastructure As Code. It’s here that cemented the fact that IAC should be the first endeavour for the summer project.
This is a great listen and a great list of resources to get started, in particular Terraform is going to be a huge player moving forward.

I will go into more detail on what I find as well as anymore great resources that I find on the way, next up expect to see a post specifically on Infrastructure As Code.
]]>