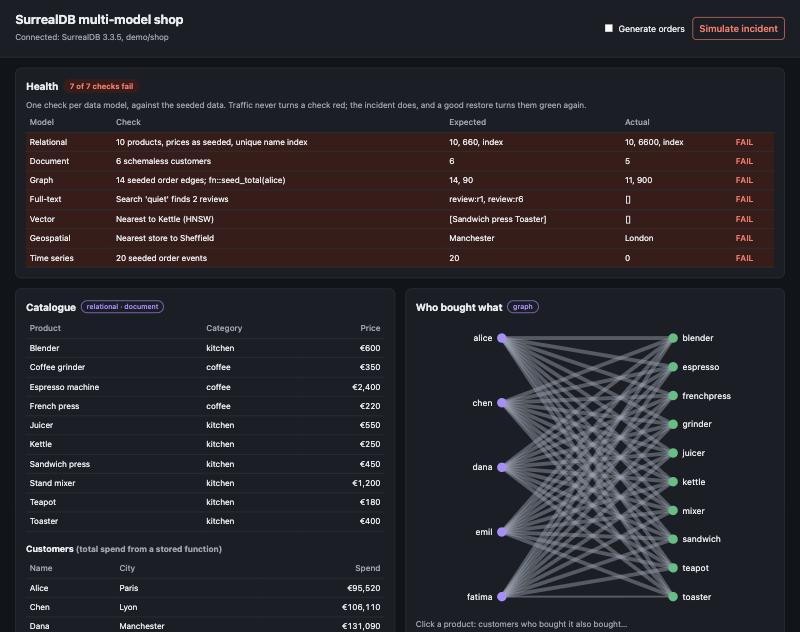
After the incident: the health panel shows 7 of 7 checks failing and every price ten times too high

I have written two long posts about protecting SurrealDB on my Talos home-lab cluster with Kasten. This is the short version. If you only read one thing: Why bother? Availability is not resilience. Kubernetes, or a managed service such as SurrealDB Cloud, keeps the database running, but it keeps serving a bad migration or a mistaken script just as faithfully. Getting the data back to a known good point, and being able to move it to another cluster, is on us. How it works Nothing pauses writes, and nothing in the restore is done by hand. Seven models, one backup In SurrealDB these are notRead More →
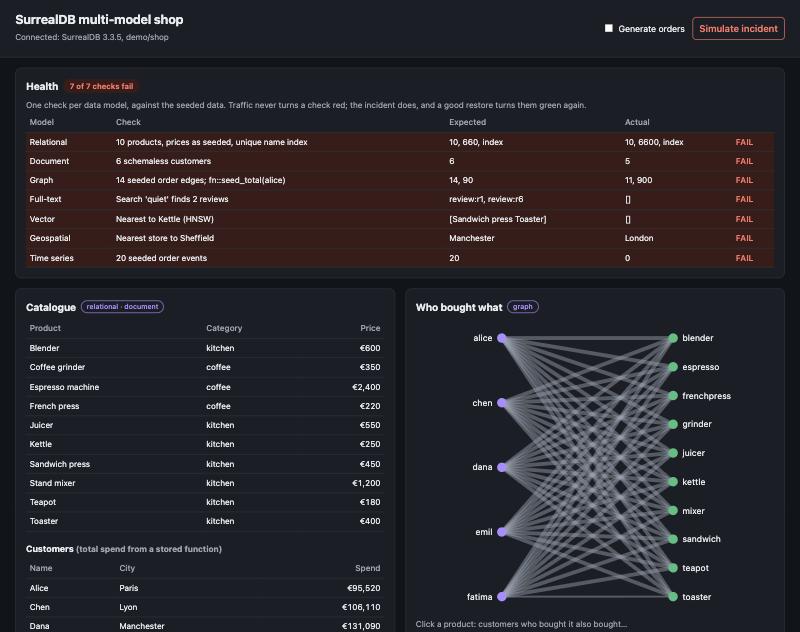
After the incident: the health panel shows 7 of 7 checks failing, prices multiplied by ten, and Bob missing from the graph

In my last post I protected SurrealDB on my Talos home-lab cluster with Kasten. The test data was deliberately tiny: five products, three customers and a handful of graph edges. That proved the method, but it left an obvious question. SurrealDB’s whole pitch is that it is one database for many data models. Does one backup really bring all of them back? So I built a small demo app that uses every model SurrealDB offers: relational, document, graph, full-text search, vector search, geospatial and time series, with live queries on top. Then I broke all of it at once and restored it. This post walksRead More →

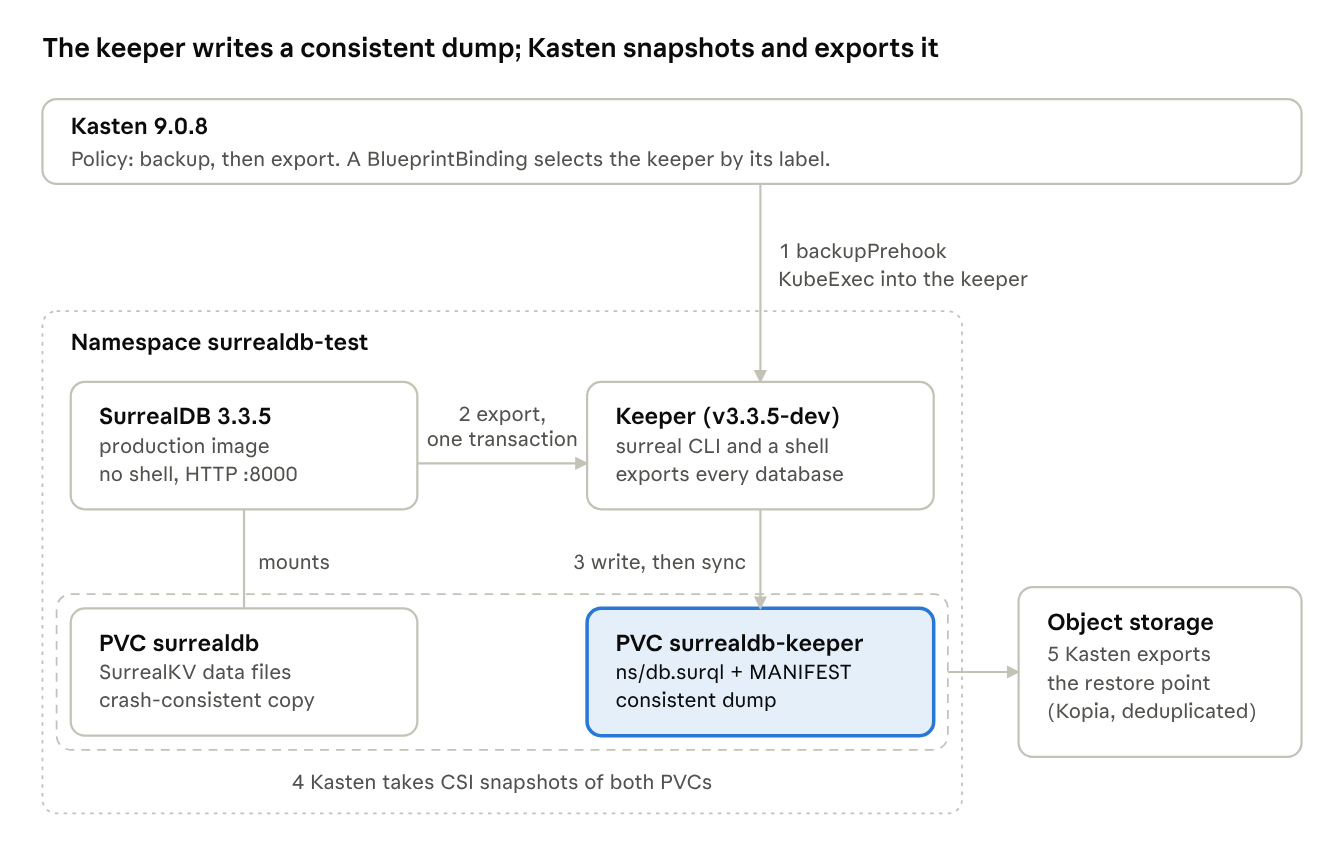
backup flow · SurrealDB, keeper and Kasten, 5 steps

I have been exploring databases a lot more in 2026, and the landscape is busy. There are “new” database vendors everywhere, on Kubernetes and as PaaS or DBaaS offerings. Some build on the shoulders of giants, mainly PostgreSQL and MySQL. Others start from a blank page. One of the blank-page databases I keep coming back to is SurrealDB. In this post I deploy it on my home-lab Talos Kubernetes cluster, load a small sample dataset, and then protect it with Kasten. The aim is a copy that is consistent at the application level, sent off-cluster to object storage, and proven by restoring it. Everything hereRead More →

Veeam just released a new plug-in for Red Hat OpenShift Virtualisation, this plug-in brings the ability to use Veeam Backup & Replication to protect your VMs on Red Hat OpenShift Virtualisation. Some people might be familiar with Veeam Kasten, Veeam Kasten provides the Kubernetes native way to protect containerised workloads and Red Hat OpenShift Virtualisation as well as SUSE Harvester (Virtualisation) as well. Between you and I, it does also work with Kubevirt but from a support perspective it is just the ones listed above for now. So what does this mean? It means if you have a blend of containerisation and VMs on oneRead More →

Omarchy is taking the Linux Desktop and developer community by storm, standing out as a serious contender for the year of the Linux Desktop. My daily driver for some time now has been Manjaro Linux, which is Arch Linux-based. A hurdle—though we don’t let hurdles get in the way of a good story and use case—is support. The Veeam Agent for Linux officially supports enterprise and LTS distributions like RHEL, Rocky, Alma, Ubuntu, Debian, SLES, and Fedora. Arch Linux isn’t on that official matrix, but spoiler alert: I have it protecting my rolling-release desktop just fine. Gotchas Support aside, a couple of things can tripRead More →

Many of us are learning new tech are doing it for one reason—to get a new job. That’s valid, but it completely changes how you study, often leading straight into tutorial hell and forgotten fundamentals. When I set out to map 90DaysOfDevOps, and now while tackling data engineering, my baseline was different. I wanted to build, break, and understand the mechanics simply because the space interested me. Whether you’re trying to pivot careers or just add a new superpower to your home lab, here is the blueprint I follow to actually make new technologies stick. Today, this challenge is amplified even more by AI. WeRead More →

Internally at Veeam we have been working on the Application Backup Repository for a few months, and since hearing about this I wanted a way to be able to demonstrate the ability to send my database backups to these NFS exports. I could not find an existing tool out there that would enable me to hit all the different database types. So in the world of AI accelerating our ideas to reality I got to work on a demo tool, simply called “DBSched” You can find out what the Veeam Application Backup Repository is here below. As I said I wanted a demo app thatRead More →

A common request I have seen within the community is ”Can Veeam protect LXC Containers in Proxmox?” and whilst this is being researched, I wanted to share a workaround that I have been using in my homelab. I posted about the Application Backup Repository We start by creating a fresh new Application Backup Repository for our LXC backups within Veeam Backup & Replication. Now we head over to our Proxmox environment to add the new NFS Export. Select the datacenter and then Storage Click add and select NFS Give it a name, The server will be your ABR Server The Export will be the pathRead More →

Last week the general availability of the Veeam Data Platform 13.1 went live and there have been some great blog posts highlighting the big ticket items that came in this minor release. Brad put together this post on the themes around 13.1 and targeted areas to continue to enable our customers to protect their ever changing estates. https://www.veeam.com/blog/veeam-data-platform-v13-1-identity-cyber-ai.html Anthony got into some of this but has a focus around the hypervisor support and continued coverage we continue to strive to help our customers protect their virtual machines. I wanted to take one of those features that I actually believe could be a pretty big dealRead More →

Yesterday we wrote down a plan. Today we started the plan. We started this course linked above, it had a bit of everything I was looking for the foundations. We are around 2 hours in and I decided that might be a good time to look back over the notes and look at the additional areas that have been mentioned already that we need to get into. I am not going to reinvent the wheel here, If you are interested then get into this first. I would say you can take the first hour and learn something. The next hour was more talking about technologiesRead More →